GeoSC reports an unscaled average post-period treated-minus-counterfactual
difference. Calling it causal requires more than estimator completion.
For treated set and measured post periods , the
target can be written conceptually as
The observed treated outcome supplies . SparseSC estimates the
unobserved from eligible donor outcomes.
A causal interpretation needs a stable outcome definition; treatment timing
and assignment measured correctly; donors unaffected by treatment; no
uncontrolled geography-specific shock aligned with launch; adequate pre-period
support for the counterfactual; and an estimand whose geography and period match
the business question. These conditions are design arguments, not outputs of
the optimiser.
GeoSC’s raw pre-trend comparison is advisory because it compares unweighted
group-mean slopes. Synthetic control instead fits a donor combination: treated
slopes near two can be matched by mixing donors with slopes zero and four,
even when most donors have slopes near zero and the raw mean comparison rejects.
This counterexample establishes a mismatch between the raw test and synthetic
matchability; it does not establish that the constructed design is causally valid.
Prespecify held-out synthetic-fit checks for model adequacy and keep the causal
identification argument separate. The distinction between a weighted comparison,
pre-intervention validation and contextual requirements is discussed in
Abadie’s methodological review.
Neither raw-trend non-rejection nor good synthetic fit proves exchangeability
or rules out launch-aligned confounding.
Only GeoSC’s experimental pre-period placebo diagnostic can be explicitly
required as an operational gate. Its procedure is unchanged and is not
calibrated here; passing it does not establish identification. The interference
screen is advisory and has no exposure model. Power addresses detection under
a simulated DGP, not identification. State each evidence source separately.
Cooldown, Seasonality, and Anticipation
Cooldown excludes observed periods between launch and measurement. It is useful
when response builds gradually, attribution matures, or short-term launch noise
is outside the estimand. It also removes data and can reduce power.
GeoSC counts observed periods. With daily data, cooldown_periods: 7 excludes
seven observed days; missing dates make that different from seven calendar
days. The resolved analysis window is persisted in validation and result
artefacts.
Cooldown does not fix anticipation. If customers or media respond before the
declared launch, the pre-period is contaminated. Move the intervention boundary
only when the behavioural timing supports it, not to improve fit.
Power’s native CLI does not apply the inference cooldown resolver. Set the
power split and simulated duration to represent the actual measurement design,
and document the translation.
Historical data should cover comparable seasonal conditions. The factor VAR(1)
DGP has no explicit day-of-week, holiday, or campaign-season terms. A long but
non-comparable history can be worse than a shorter seasonally relevant window;
use pre-specified sensitivity checks.
Design Rejection
GeoSC should reject or defer a design when the requested causal statement is not
supported. At minimum, stop when:
treatment, outcome, geography, or measurement window is unresolved;
treatment exposure cannot be separated from donors;
the panel cannot satisfy the explicit data contract;
no substantively eligible donor pool remains;
pre-period fit is materially inadequate or dependent on an implausible donor;
placebo support cannot resolve the pre-specified alpha;
power is inadequate for the commercially plausible effect range;
simulation failures or DGP sensitivity make MDE unstable;
required assumption checks fail or inference status is failed;
conclusions reverse under small, equally defensible specifications.
Some failures can be repaired by changing geography, outcome, history, duration,
or eligibility. That creates a new design and requires a new power assessment.
If no repair is defensible before treatment, document the experiment as
descriptive or infeasible. A forced estimate is not a more helpful answer.
Donor Quality
Donor quality has two distinct meanings in GeoSC.
The donor stage measures pairwise pre-period similarity. Correlation captures
co-movement; RMSE and MAPE capture level error; normalised DTW captures temporal
shape. Composite scores are relative within each treated geography and support
screening. They do not estimate final counterfactual weights.
Inference measures joint synthetic-control fit. Several individually modest
donors can combine well, while a highly correlated donor can receive little
weight. Review fitted pre-period error and the SparseSC weight distribution.
Strong screening scores do not establish donor exchangeability. Eligibility
also requires no treatment exposure, comparable outcome measurement, and no
post-launch shock that differentially moves the donor. Conversely, poor overlap,
incomplete metrics, concentrated recommendation weights, or weak joint pre-fit
are direct reasons to reconsider the design.
Donor selection must be outcome-blind with respect to the measured post period.
Changing the pool after seeing lift invalidates ordinary interpretation unless
the search and multiplicity are explicitly modelled.
Frequently Asked Questions
Is a donor the same as a control?
A donor is an eligible control geography that can contribute to a synthetic
counterfactual. In code, power calls all non-treatment units controls. Preserve
the eligibility distinction in design documentation.
Do donor recommendations flow into inference?
No. The pipeline runs stages independently. Filter and version the panel if the
donor screen changes the eligible universe, then rerun affected stages.
Is GeoSC power simulation-based?
Yes. It estimates a factor-VAR DGP from the pre-period, simulates post-periods,
injects effects, calls SparseSC, and counts p-values below alpha. It is more
computationally intensive than a closed-form MDE but not automatically more
accurate.
Does power use the complete inference workflow?
No. It uses the SparseSC estimator and detection rule inside simulation but has
a narrower configuration and does not run inference data policies, cooldown,
assumption gates, or result processing.
Why can estimated power decrease at a larger effect or duration?
Finite Monte Carlo estimates can fluctuate. Large reversals can also indicate
failures, coarse placebo support, a weak DGP, or specification sensitivity.
Increase simulations and investigate; do not label an empirical rolling-window
diagnostic a theoretical monotonic power curve.
What does MDE mean here?
For a duration, it is the smallest valid effect on the tested grid reaching
configured target_power. It is not expected campaign lift and is not
interpolated.
How is a relative effect injected?
GeoSC multiplies one pooled mean across treated units and all pre-periods by the
relative effect, then adds the same absolute path to each treated unit.
What does valid mean in power output?
At least one simulation succeeded and failure rate did not exceed the threshold.
It says nothing about DGP plausibility or causal identification.
What is the top-level inference p-value?
It is a two-sided, add-one-corrected in-space placebo p-value for the absolute
average post-period effect. It is not a post/pre MSPE-ratio p-value.
Can a small donor pool produce significance?
Only at the resolution allowed by its effective placebo count. The smallest
step is 1 / (n_placebos + 1) under the implemented calculation.
Does status: ok prove the campaign caused lift?
No. It means the software result contract completed. Identification depends on
eligibility, isolation, measurement, timing, pre-fit, and sensitivity evidence.
Does GeoSC calculate ROI or iROAS?
No. Combine a defensible incremental outcome with campaign cost and the correct
commercial value or margin definition downstream.
Does GeoSC support GPU inference?
No. Optional CuPy work is limited to supported unseeded power DGP paths. Seeded
power and main SparseSC inference are CPU-based.
Method Comparisons
Compare estimands and decision rules before comparing numbers.
Time-based regression on aggregated treatment and control signals
Model-based intervals; design power depends on the implementation
Stable treatment-control relationship, match quality, model form, assignment constraints
Meridian GeoX
Randomised or stratified assignment with TBR inference at the documented launch boundary
Product-specific
Randomisation, balance, TBR stability, and delivery integrity
Meta GeoLift
Augmented synthetic control with generalised synthetic-control components
Conformal and package-specific procedures
L2 imbalance, augmentation model, market selection, test fit
Bayesian causal-impact tools
Structural time-series counterfactual
Posterior distribution
Prior/model fit and posterior predictive behaviour
GeoSC’s native power module is simulation-based, but that does not imply a TBR
or GeoX MDE is necessarily analytic; implementations vary. GeoSC repeatedly
simulates a factor-VAR post period, injects effects, and calls SparseSC. A TBR workflow may
use a fitted treatment-control regression, residual variance, analytic formula,
resampling, or simulation.
Before comparing MDEs align outcome and transformation, treatment geography,
control eligibility, pre-period, measurement and cooldown windows, lift
denominator, effect pattern, alpha, target power, one- or two-sided rule,
failure handling, and whether placebo assignments are sampled. Before comparing
effects align the estimand, scale, aggregation, and uncertainty interpretation.
A material discrepancy is a diagnostic. Decompose it rather than averaging the
answers or assuming the larger MDE is conservative. GeoSC is useful when
individual donor diagnostics, Python operation, and auditable artefacts matter;
it is not automatically superior to a well-specified regression design.
These references describe their respective implementations. They do not imply
that an internal or modified workflow uses the same defaults.
Multi-Treatment Designs
GeoSC supports several treated geographies, but interpretation and computation
change.
The top-level effect is joint across the treated set; it is not a separate ATT
for each geography. Placebo assignments must contain the same number of control
units as the treated set, giving possible assignments.
Each physical control contributes one residual path, so two treated units and
ten controls give 45 assignments. Controls with identical residual values
remain separate geographies. An assignment cannot contain the same geography
twice, although separate sampled assignments can repeat.
SparseSC work can grow rapidly, so sparse_sc_max_n_pl may trigger sampling.
There must be at least as many controls as treated units. This subset
feasibility rule does not establish sufficient p-value resolution or satisfy
the separate cross-fitting requirements; a larger control pool may be needed.
Power injects the same absolute effect path into every treated unit, based on
the pooled treated pre-period mean. This is not unit-specific proportional lift.
When treated units have very different outcome levels, supplement the standard
run with a carefully labelled sensitivity analysis or avoid describing the
injected effect_size as each unit’s own percentage lift.
All treated units must share one launch date equal to intervention_date.
GeoSC checks supplied dates before excluding cooldown periods and retiming the
estimator to the common measurement start. Staggered dates and a shared date
that differs from intervention_date are rejected. The private SparseSC
estimator also rejects staggered and dose-normalised requests; they require
different assignment rules.
Regenerate multi-treatment p-values, intervals, and power outputs produced
before the distinct-geography correction, including runs with a small placebo
cap. Earlier construction replicated the control block once per treated unit;
a low cap could hide the count mismatch without repairing the reference set.
The correction preserves fitted weights and point effects. It does not qualify
the placebo exchangeability assumptions or establish simulation calibration.
Placebo Inference
GeoSC uses SparseSC in-space placebo inference because geo experiments often
have too few treated units for conventional large-sample approximations.
For each treated-sized subset of eligible controls, SparseSC constructs an
honest placebo effect. The top-level p-value compares the absolute average
treated effect with the absolute average placebo effects and applies an add-one
correction. It is two-sided.
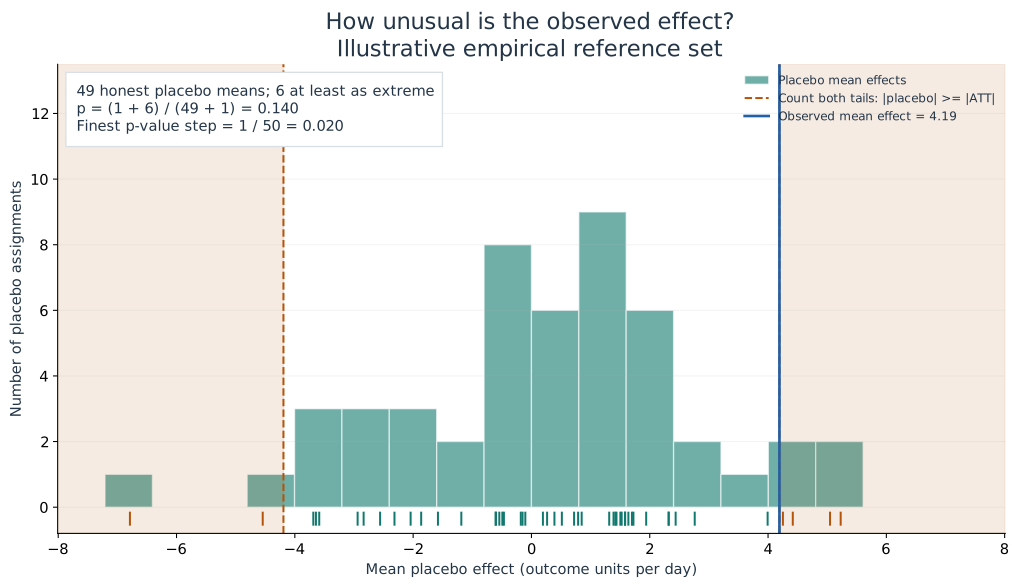
Read the empirical reference set
This uses the same synthetic example
as the counterfactual chart. With one treated geography and 49 controls, all 49
single-control placebo assignments are enumerated. The bars show honest placebo
mean effects from the native result; marks below the axis locate each value.
Orange shading identifies both tails where the absolute placebo mean is at
least as large as the absolute observed mean. The printed numerator includes
one for the add-one correction. Histogram bins are only a display choice;
counts and the p-value are computed from individual placebo values, including ties.
The finest p-value step is 1/50, or 0.02, in this example. No Gaussian distribution
is fitted. The figure explains the implemented comparison; it does not establish
exchangeability or statistical calibration. The numerical source
records the observed mean, every placebo mean and the counted exceedances.
Each eligible physical control appears once in the reference matrix. A subset
contains distinct geographies, even when some residual paths have equal values.
All treated units share one launch and measurement window.
The unchanged backend uses ten honest cross-fitting folds, so GeoSC requires
at least ten effective controls before SparseSC fitting. At the ten-control
boundary, each fold holds out one control and retains nine for fitting in the
retrospective fast-path fixture. This is an operational feasibility check,
not a qualification of error rates or donor exchangeability. Adding periods
or treated geographies does not increase the control count. Match-space CV
settings have separate training-size constraints; lowering sparse_sc_cv_folds
does not change honest cross-fitting.
When feasible assignments exceed sparse_sc_max_n_pl, SparseSC samples
assignments using sparse_sc_placebo_seed; otherwise it enumerates them. The
result reports the possible and effective counts and labels the mode exact,
sampled, or unknown.
Here exact means exhaustive enumeration of the supported physical-geography
assignment set; it does not assert exact causal calibration. Sampled draws
can repeat an assignment across draws, so the effective count is the number of
draws, not necessarily the number of unique assignments.
Finite support matters. With effective placebos the nominal resolution
is . If this exceeds alpha, significance at that alpha cannot be
attained. Sampling adds reference-set variability even when the optimiser is
stable; preserve the seed.
The p-value is calibrated only relative to the placebo assignment logic and its
exchangeability assumptions. Non-comparable donors, spillover, differential
measurement changes, or poor pre-fit can make a numerically small p-value
misleading. SparseSC placebo intervals are likewise finite-reference-set
quantities, not model-free guarantees.
Power and MDE Methodology
GeoSC power is a simulation-based design diagnostic. For each effect and
duration, let N be attempted simulations, S successful estimates, F=N-S failed
estimates, and R successful estimates with p < alpha. Ordinary power is R/N and
is available only when F=0. If any draw fails, primary power and its Wilson
interval are unavailable, and the row cannot support ordinary MDE recommendations.
The successful-draw rate remains explicitly named:
Failed draws have unknown rejection outcomes. The observed all-attempt rate
therefore has completion bounds:
For eight rejecting successes and two failures, conditional rejection is 100%
and the completion bounds are 80% to 100%; ordinary power is unavailable. These
are missing-outcome completion bounds for the simulated sample, not confidence
intervals or bounds on true population power. When every draw fails, conditional
rejection is unavailable and the completion bounds are [0,1]. When none fails,
the bounds collapse to the observed rate, while Monte Carlo uncertainty remains.
A row is valid only when its complete positive integer attempt count contains
zero failures. This does not establish DGP credibility, absence of future
failures, identification, or statistical calibration. There is no permissive
failure-rate override; power_failure_rate_threshold is retired.
Implemented workflow
For every effect-duration grid point, GeoSC:
pivots the long CSV to a unit-by-period matrix and sorts parsed dates with
their outcomes at the shared calculator boundary;
uses periods before treatment_date as the fixed observed pre-period;
demeans each unit, fits an SVD factor model, and estimates factor dynamics;
simulates a post-period panel;
computes one baseline as the mean across all treated units and all pre-periods;
multiplies that pooled baseline by effect_size and applies the resulting
same absolute effect path to every treated unit;
appends simulated post data to the observed pre-period;
calls SparseSC with treated periods at the split and counts
results.p_value < alpha.
The direct calculator excludes rows outside its declared treatment and control
sets before DGP fitting, retaining eligible rows in source order. File-driven
power defines those sets as the configured treated geographies and all other
CSV geographies. Unit identifiers must be unique and non-missing, and the two
sets must be disjoint and present in the panel.
This denominator means a configured 10% lift is relative to the pooled treated
pre-period mean. It is not a separate 10% of each treated unit’s own baseline.
The output records the baseline and full absolute injection.
The power loop uses the SparseSC estimator and its top-level placebo p-value,
but it is not identical to geosc infer. It does not run inference’s panel
policies, cooldown resolver, assumption checks, CI configuration, result
processor, or full SparseSC config surface. “Same inference path” is therefore
too strong; align panels and settings explicitly.
Power supports retrospective fast RidgeCV detection and shares inference’s
method/CV option builder for that path. It rejects other method requests and
simulation-owned window, CI or placebo-seed keys rather than discarding them.
Accepted CV controls are consumed by the native learner and recorded as JSON
estimator_settings in each row. Both stages retain their independent YAML
and placebo caps, so align the intended procedure explicitly.
Ignored lasso controls are retired. Match-space scoring uses a documented
continuous multi-output regression subset; recognising a sklearn scorer name
alone is insufficient because an incompatible scorer can yield all-NaN CV
scores without raising an exception. Native checks verify the supported
criteria on a manufactured panel; they do not establish campaign calibration.
Each successful simulation must return a finite real numeric p-value in
[0, 1]; booleans, strings, arrays, missing values and out-of-range values count
as failures. The original scalar is used for range checks and the strict
p_value < alpha comparison, avoiding rounding across a boundary. Invalid
outputs appear in n_invalid_p_values; other failures appear in
n_estimation_failures, and both contribute to n_failed.
The diagnostic conditional_power divides detections by successful estimates.
It must not be substituted for ordinary power or used to select an MDE. A failed
row remains unavailable even if the lower completion bound exceeds target power;
no failure-handling estimand is silently introduced. The corrections do not
establish empirical size, coverage or power calibration.
Effect patterns
constant and immediate: full absolute effect in every simulated period;
ramp: linear sequence from zero to full effect, inclusive;
decay: full effect followed by decay;
any other value: configuration error.
The 0.1 decay rate is not configurable in version 0.4.0.
Grid-based MDE
For duration and target power , GeoSC reports the smallest valid
tested effect that reaches the target:
target_power defaults to 0.80 in the CLI and pipeline but is configurable. No
interpolation is performed. If no effect reaches the target, MDE is above the
tested range.
Monte Carlo uncertainty
The CSV includes a Wilson interval around the estimated detection proportion.
Its confidence setting uses the configured alpha. This interval describes
finite simulation uncertainty, not DGP misspecification, donor-selection
uncertainty, or future-campaign uncertainty. If it straddles target power,
increase n_simulations before making a threshold decision.
Worked output
duration
effect_size
power
interval
failure_rate
valid
28
0.05
0.42
0.36–0.48
0.00
true
28
0.10
0.76
0.71–0.81
0.00
true
28
0.15
0.91
0.87–0.94
0.00
true
35
0.10
0.84
0.79–0.88
0.00
true
42
0.10
unavailable
unavailable
0.25
false
At 80% target power, the 28-period grid-based MDE is 15% and the 35-period MDE
is 10%. The 42-period row is withheld because some draws failed.
Power is computationally intensive because total work scales approximately with
effect sizes × durations × simulations × SparseSC fit and placebo cost. This
differs from a closed-form regression MDE, but computational intensity is not by
itself evidence of better calibration.
Power DGP Assumptions
GeoSC estimates its power data-generating process (DGP) from the pre-period
outcome matrix.
Each unit is demeaned. Singular value decomposition produces factor loadings
and factor scores. When rank is automatic, GeoSC chooses the first rank reaching
about 80% cumulative singular-value variance, bounded by
power_dgp_max_rank and a short-panel VAR feasibility cap. It then estimates a
VAR(1) intercept, transition matrix, and Gaussian innovation covariance on the
factor series.
Simulation draws the initial factor state from the estimated marginal normal
distribution; it is not conditioned on the final observed factor state. Later
states follow the fitted VAR(1). Outcomes combine fixed unit loadings, simulated
factors, stored unit means, and independent Gaussian idiosyncratic noise with
one pooled residual standard deviation.
Consequences:
cross-unit dependence is represented through common factors;
lag-one factor dependence is represented;
calendar seasonality is not modelled explicitly;
the fitted VAR transition is not constrained to be dynamically stable;
idiosyncratic variance is homoskedastic across units and periods;
non-Gaussian tails, structural breaks, intermittent zeros, and conditional
start-state dynamics may be poorly represented;
rank selection is a heuristic, not cross-validated DGP truth.
Validate simulated moments and time-series behaviour against the use case. Run
sensitivity to history, rank, effect pattern, and eligible controls. If design
decisions change materially, report DGP dependence rather than one definitive
MDE.
SparseSC Estimator
GeoSC’s only implemented estimator selector is sparsesc. SparseSC learns a
regularised match space and donor weights from pre-treatment outcomes and
optional covariates.
Conceptually, it chooses unit weights and match-space weights to
reduce treated-versus-synthetic pre-period discrepancy subject to regularisation:
This is an explanatory simplification, not a line-by-line restatement of every
vendored optimisation path. With sparse_sc_fast_estimation: true, GeoSC calls
the vendored fast path, which uses RidgeCV-backed match-space machinery. The
full path uses SparseSC’s penalty search and coordinate-descent machinery.
Regularisation controls overfit; it does not make an ineligible donor valid.
Inspect pre-fit, fitted unit weights, weight concentration, and sensitivity to
substantive donor exclusions. The selected_weight from GeoSC’s donor stage is
not ; fitted weights are exposed in inference diagnostics.
The package vendors a pinned, locally governed SparseSC fork. See
Vendored Dependencies for provenance.
Spillover, Contamination, and Concurrent Media
Synthetic control requires the donors to represent untreated outcomes. This can
fail when audience delivery crosses boundaries, national media reaches both
groups, travellers move between geographies, retail or supply changes differ by
region, or another campaign starts near treatment.
Concurrent activity is not automatically fatal. A national or business-as-usual
channel can be part of the baseline if its effect and delivery are sufficiently
common across treated and donor geographies. Differential delivery correlated
with treatment is the problem. Record channel, dates, spend or delivery where
available, targeting logic, and expected geographic reach.
GeoSC’s interference screen compares outcome behaviour and can return signal,
no_signal, or indeterminate. It has no exposure model and cannot establish
whether media caused the pattern. Use campaign logs, geographic delivery data,
and domain evidence. Keep the screen advisory.
If contamination is material and cannot be represented or excluded, reject the
design or change the estimand. Do not reinterpret contaminated donors as valid
because pre-period fit was good.
Synthetic-Control Formalism
Let be the outcome for unit and period . Let
denote treated units, eligible donors, and
the last pre-treatment period after any window resolution.
For one treated unit, a synthetic counterfactual has the form
The maintained retrospective fast estimator uses pre-treatment features and
post-period control outcomes to learn the match space. It does not fit to the
treated post-period outcomes. The period effect is
and GeoSC’s top-level unscaled ATT is the average of that effect over measured
post periods:
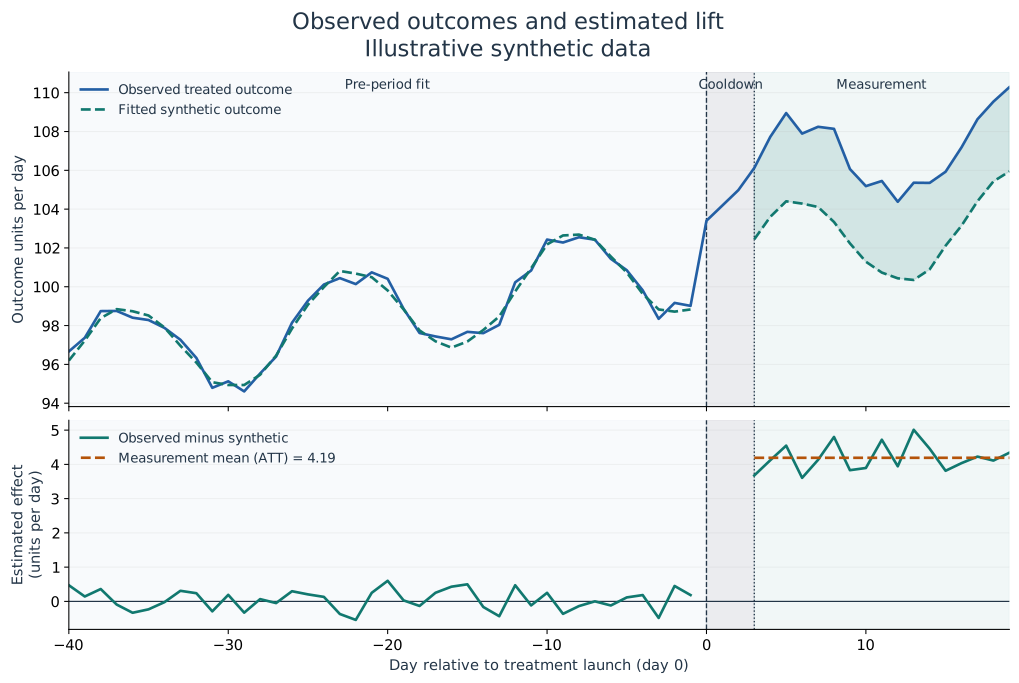
Read the fitted counterfactual
This illustrative synthetic example has one treated geography, 49 eligible
controls, 40 pre-period days, three cooldown days and 17 measured days. The
upper panel compares observed outcomes with the fitted synthetic trajectory.
The lower panel shows their difference; its dashed line averages only measured
days. The three cooldown days are excluded from fitting and the reported effect,
so the synthetic line has a gap there. The filled area between the upper lines
shows an outcome difference, not a confidence interval.
The generator adds four outcome units per day after launch, but the chart shows
the estimated effect rather than substituting that known injection. Its
counterfactual and placebo figures come from the same native GeoSC analysis.
See the numerical source and
reproduction instructions.
This is an explanation of the calculation, not a calibration study or campaign result.
The implementation also supports multiple treated units. SparseSC constructs a
joint treated effect and an in-space placebo reference set formed from treated-
sized subsets of controls. With controls and treated units, the
exhaustive assignment count is
GeoSC’s top-level p-value is not a post/pre mean-squared prediction-error
ratio. If is the average placebo effect for assignment
, SparseSC uses the two-sided absolute-effect comparison with add-one
correction:
where is the effective exhaustive or sampled placebo count. The finest
attainable step under this calculation is . The result is an
empirical comparison against the eligible placebo assignments; its causal
meaning depends on the design.