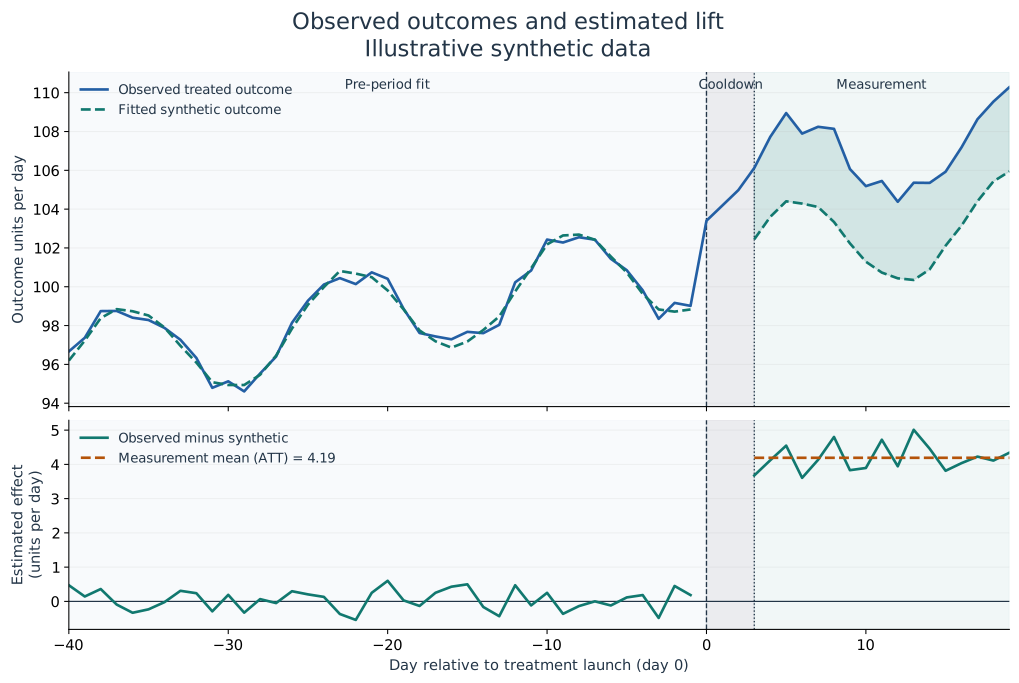
Average difference, in outcome units per observed period, between treated
outcomes and their SparseSC counterfactual over the declared measurement
window for the declared treated geographies.
GeoSC labels this att_unscaled. The top-level att is the average across the
post-period effect path. If several geographies are treated, the SparseSC
procedure forms a joint treated effect; do not describe the result as a
unit-specific effect unless a separate analysis supports that claim.
Set:
intervention_date_str: first observed treatment period;
cooldown_periods: observed periods after launch excluded from measurement;
optional measurement_start_date_str: explicit start that must agree with the
cooldown calculation;
min_pre_treatment_periods and min_post_treatment_periods: admissibility
thresholds where supplied.
Cooldown periods are neither pre-period fit data nor measured post-period data.
They count observations, not calendar units. A seven-period cooldown is seven
days only for a complete daily panel.
Pre-specify the end of measurement by trimming the input panel to the intended
window. The shipped inference config has no active end_date key.
Define Treatment and Donor Eligibility
Create and freeze an eligibility table before running GeoSC. Treat it as the
analysis-universe contract: it records which geographies are treated, which
untreated geographies are eligible controls, which geographies are excluded, and
why.
Use one row per geography:
Column
Purpose
unit_id
Geography identifier used in the input panel.
role
treated, eligible_control, or excluded.
included_in_panel
Whether the unit is present in the versioned panel used by a stage.
reason
Design reason for inclusion or exclusion.
decision_date
Date the eligibility decision was made.
owner
Person or team accountable for the decision.
contamination_notes
Known campaign, operational, or measurement contamination.
leakage_notes
Geographic adjacency or audience leakage concerns.
Example:
unit_id
role
included_in_panel
reason
decision_date
owner
contamination_notes
leakage_notes
region_ne
excluded
false
Adjacent to treatment region and exposed to overlapping out-of-home media.
2026-08-05
Measurement lead
Same creative ran during the test window.
Commuter leakage into treatment area.
Eligible controls should be unaffected by treatment, measured consistently, and
plausible counterfactual contributors. Pre-period correlation and donor-screen
scores are diagnostics; they are not eligibility rules and do not prove
exchangeability. Exclude geographies only for design reasons established before
reviewing post-treatment outcomes.
Freeze the Universe
Define treated units and the first observed treatment period.
Remove contaminated, leaking, inconsistently measured, or otherwise
ineligible controls.
Materialise the approved treated units and eligible controls as a versioned
panel.
Run power, donor evaluation, and inference from that versioned panel.
If donor screening changes the eligible universe, create a new panel version
and rerun the affected stages.
Do not tune exclusions, treatment dates, or donor membership after seeing
post-treatment lift. That creates a different design and invalidates ordinary
interpretation unless the search and multiplicity are explicitly modelled.
What GeoSC Includes
Power treats every non-treatment unit in its input as a control. Donor
evaluation scores every eligible non-treatment unit in its own input. Inference
uses the controls in its prepared panel, where controls are units without a
treatment period. GeoSC does not automatically apply donor recommendations to
the other stages.
For several treated geographies, confirm that the eligible control pool can
support joint in-space placebo assignments: with controls and
treated units, the exhaustive assignment count is , provided
. If the eligible control pool is too small, placebo inference is
infeasible or too coarse for the planned alpha.
Revisit eligibility, geography level, outcome, and comparable history.
Coarse p-value granularity
Too few effective placebo assignments
Add eligible controls or reduce treated count only if the design permits it.
Fewer than ten retained controls
Infeasible ten-fold honest cross-fitting
Add eligible controls and check data-policy drops; changing match-space CV folds cannot enable this pool.
Dominant fitted donor weight
Counterfactual depends on one geography
Audit that donor and run exclusion sensitivity.
High power failure rate
SparseSC or DGP instability
Inspect exceptions, rank, panel completeness, and placebo feasibility.
High grid-based MDE
Noise or weak counterfactual relative to plausible lift
Redesign duration, outcome, treated scale, or method before launch.
Interference signal
Outcome changes among controls are compatible with contamination
Investigate exposure using campaign and geographic evidence; the screen is not causal proof.
Result partial
Missing uncertainty or warnings
Resolve the stated fields before decision use.
Do not tune exclusions, dates, or donors by searching for significance. If the
remedy changes the design, rerun power and record the new specification.
Evaluate Donors
Run donor evaluation on pre-treatment data after applying substantive
eligibility exclusions.
The evaluator aligns each treatment-donor pair by time, then calculates Pearson
correlation and its p-value, root mean squared error (RMSE), percentage RMSE,
mean absolute percentage error (MAPE), and normalised dynamic time-warping
(DTW) distance. It normalises metrics within each treated geography, combines
them using adaptive weights, and ranks complete rows.
Review:
overlap_count, treatment_coverage, and donor_coverage before scores;
metrics_complete and metric_failure_reasons;
correlation, rmse, mape, and dtw, not only composite_score;
warning_flags, quality bands, concentration, and effective donor count;
maps only as a geographic diagnostic, not as proof of comparability.
selected_weight is normalised from positive composite scores among the
recommended donors. Its role is design_stage_recommendation_weight; it is not
a fitted SparseSC counterfactual weight.
The evaluator’s output is a screening artefact. If it changes the donor pool,
filter the canonical panel and rerun power and inference. To render maps, see
Use Shapemaps.
DTW standardises each pair’s finite, timestamp-aligned overlap using its own
mean and population standard deviation. FastDTW uses scalar absolute local cost,
a fixed approximation search radius of one, and divides the resulting distance
by the overlap count. Constant series become zero vectors. The radius controls
the approximation neighbourhood around a recursively estimated path; it does
not bound the displacement between aligned dates.
Version 0.4.0 replaces the history-dependent approximation radius. This can
change DTW, composite rankings, recommendation weights and seasonality_score
(which aliases normalised DTW). Regenerate recommendations and inspect the
underlying metrics. Backend and radius are recorded in quality JSON; rankings
are screening outputs and have no calibrated acceptance guarantee.
How to Use Shapemaps
GeoSC donor-stage maps use shapemap_file to read a GeoPandas-compatible vector
file and shapemap_id_column to choose the geography ID used for joins. The
values in that ID column must match the unit IDs used in your experiment data,
such as DMA IDs, postcode districts, postcode areas, or another market key.
The inference and power stages do not consume shapemap configuration.
Built wheel and sdist installs do not include the repository-local shapemap/
directory. Packaged users should provide map files from their own runtime
environment.
GeoSC can read formats supported by GeoPandas, including GeoJSON, TopoJSON,
Shapefile, and GeoPackage inputs when the local geospatial stack supports them.
Repository-local shapemap examples are available for common markets:
shapemap/uk/postcode_areas.geojson
shapemap/uk/postcode_districts.geojson
shapemap/us/dma_legacy_normalized.geojson
shapemap/fr/fr_nuts3.geojson
shapemap/de/de_nuts3.geojson
shapemap/uk/meta_commuting_zones.geojson
shapemap/us/meta_commuting_zones.geojson
shapemap/fr/fr_meta_commuting_zones.geojson
shapemap/de/de_meta_commuting_zones.geojson
These are source-checkout assets. They are not included in built wheel or sdist
artifacts.
Meta Commuting Zones are also available as optional geographies for
Meta-aligned study design. They are commuting/economic zones, not Meta
ad-targeting boundaries.
UK Postcode District Example
For UK production workflows, postcode district is often the practical market
geography:
Do not commit or distribute postcode geometry unless the source license permits
that use. The repository records shapemap provenance policy in
shapemap/README.md and shapemap/manifest.yaml.
For UK data:
OS Code-Point Open is an open postcode unit point dataset, not polygon geometry.
OS Code-Point with Polygons is the appropriate official polygon source when
you have the necessary access and licensing.
ONS Postcode Directory is useful for postcode-to-geography lookup workflows.
Troubleshooting
If donor maps do not highlight treatment or donor units:
confirm the shapemap contains the configured shapemap_id_column
confirm the shapemap ID values exactly match the experiment unit IDs
normalize both sides to the same case and spacing convention
confirm the file can be opened by geopandas.read_file
scripts/validate_shapemap.py reports missing expected IDs, duplicate IDs,
blank IDs, null or empty geometry, invalid geometry, row counts, unique ID
counts, and the detected CRS.
Prepare an Input Panel
Use a long CSV with one row per geography and observed period. The inference
loader requires configured date, geography, and outcome columns; treatment is
defined in YAML, not read from a treatment flag in the CSV.
Required checks
Use stable geography identifiers and one geographic level.
Use a regular time interval appropriate to the campaign and outcome.
Confirm that every intended unit-period has one finite outcome.
Make the intervention date an observed period.
Preserve enough observations before and after the resolved measurement start.
Use a consistent outcome definition, currency, attribution window, and data
production process across geographies and time.
Inference defaults to duplicate_policy: error and
missing_outcome_policy: error. Alternative policies are explicit analytical
decisions. mean or sum changes duplicate rows before pivoting;
drop_unit, drop_period, or impute_with_report changes the estimable panel.
With impute_with_report, interpolation and endpoint filling use observations
from the same pre-treatment, cooldown, or measurement window. A geography with
no observed outcome in a window fails; supply data or choose an explicit drop
policy. The method uses observed-period positions rather than elapsed time, so
keep the observation cadence appropriate to the analysis.
Optional covariates are numeric pre-period baseline means. They use only
retained outcome periods, average duplicate records within a period before
averaging periods, and skip missing covariate observations. Every unit/feature
needs an observed finite baseline. For direct-data runs, prepare this baseline
table before passing covariates_df; GeoSC cannot infer its source dates.
Do not use locale-dependent date parsing in an audited run. After execution,
review data_validation.json; a successful model does not supersede a failed
data contract.
Produce a Stakeholder Summary
Lead with the decision and its conditions. A compact summary should include:
treated geography, outcome, launch, cooldown, and measurement dates;
eligible donor universe and material exclusions;
design-stage MDE at the stated target power and plausible lift range;
inference status, ATT in outcome units, interval, p-value, and placebo count;
pre-period fit and donor concentration;
concurrent media, spillover, data, and sensitivity caveats;
a clear recommendation: proceed, interpret cautiously, redesign, or reject.
Example:
GeoSC estimated average incremental revenue of £X per week against the
pre-specified SparseSC counterfactual over dates A–B. The two-sided in-space
placebo p-value was P using N placebo assignments; the interval was [L, U].
Interpretation is conditional on the recorded donor-eligibility and treatment-
isolation assumptions. The design-stage grid-based MDE was M% at T% target
power, so effects below M% were not reliably detectable under the fitted DGP.
Do not translate statistical significance into ROI without campaign cost and a
commercial value definition. Do not describe status: ok as proof of causal
validity.
Use the interval level recorded in ci.level, independently of the configured
significance threshold. An 80% average-ATT interval must not be labelled 95%,
and its bounds must remain in the ATT’s unscaled outcome units. Scaled
diagnostic bounds cannot fill missing primary uncertainty. The uplift plot’s
horizontal band concerns average ATT uncertainty, not coverage of the effect
path.
For partial results, retain warnings and state which quantities remain
available. For failed or unknown status, report errors and unavailable
inference instead of interpreting retained diagnostic numbers. Read
significance_available before the stored significant flag; an unavailable
decision is not evidence of no effect. The maintained renderers apply these
rules consistently and the HTML report escapes artifact-derived text.
Run Inference
Freeze the panel and inference YAML before viewing post-treatment results, then
run:
Use --data to override only the CSV path and --no-create-plots to suppress
plotting. The command returns non-zero when the stage raises an error or the
result status is failed.
Review outputs in this order:
data_validation.json for panel construction and window metadata;
assumption_validation.json for advisory pre-trends/interference and any
explicitly requested experimental pre-period placebo gate;
geolift_results.json for status, unscaled ATT, p-value, interval, placebo
count, granularity, warnings, and errors;
geolift_diagnostics.json for pre-fit and fitted donor-weight diagnostics;
uplift_timeseries.png as a visual diagnostic.
Summary intervals use the recorded ci.level and unscaled nested bounds.
Disabled or unavailable primary intervals remain unavailable, even when scaled
diagnostics exist. Partial plots display their limitations; failed or incomplete
primary results cannot generate uplift plots. Regenerate older dictionaries
missing status, estimand or nested interval metadata rather than assigning a
default confidence level. See the result contract.
Describe the result as an estimated difference from the configured SparseSC
counterfactual. Causal interpretation requires defensible donor exchangeability,
treatment isolation, stable measurement, timing, and absence of material
unmodelled shocks. The advisory interference screen cannot prove or disprove
spillover.
Read the estimated effect
This synthetic example illustrates the distinction between the outcome path,
period effects and their measurement-period average. It is not an output from
your campaign. Read the worked explanation
before interpreting the equivalent diagnostics in your own run.
Run Power Analysis
Define a plausible effect grid and duration grid, then run:
geosc power --config data-config/power_analysis_config.yaml --jobs -1
Use a fixed random_seed for an audited run. Seeded runs use CPU simulation
paths. Start with a small n_simulations only to debug the configuration, then
increase it until Monte Carlo intervals are adequate for the decision.
For each row:
require valid: true;
inspect failure_rate and warnings;
compare power with its Wilson interval;
verify the DGP rank, explained variance, backends, placebo support, and
injection metadata;
interpret MDE as the smallest tested effect reaching target_power for
a duration.
GeoSC does not interpolate between effect sizes. If no grid value reaches the
target, report MDE as greater than the maximum tested effect. The CLI’s default
planning threshold is 80%; it is configurable through target_power and is not
a statistical property of SparseSC.
Power uses the SparseSC estimator and p-value detection rule inside each
simulation, but it does not execute the full inference workflow. It does not
run inference data policies, cooldown resolution, assumption checks, result
processing, or plotting. Align the power input panel and intervention split with
the intended inference design yourself.
Run Sensitivity Analysis
Pre-specify a small set of defensible perturbations:
alternative comparable pre-period windows;
exclusion of a substantively suspect or dominant donor;
plausible cooldown or measurement-start choices;
DGP rank and effect-pattern choices for power;
outcome definitions fixed before post-period inspection;
eligible geography aggregations justified by media delivery and spillover.
For each run, save its panel hash, config, artefacts, and rationale. Compare ATT,
intervals, p-values, pre-fit, donor weights, placebo support, MDE, and failure
rates. Distinguish robustness to a design choice from fishing over arbitrary
specifications.
If the decision changes under small, equally defensible perturbations, report
the result as specification-sensitive. Do not average incompatible estimands.
Run the Pipeline
Place the three canonical stage configs in one directory, then point the
pipeline at any one of them:
The required filenames are power_analysis_config.yaml,
donor_eval_config.yaml, and geolift_analysis_config.yaml. The command runs
power, donors, then inference and writes Markdown and HTML summaries by default.
--output-dir creates the legacy stage subdirectories below the supplied root.
--jobs and --use-gpu are passed as runtime overrides, subject to each
stage’s support.
The pipeline is an orchestrator, not a design-state engine. Donor
recommendations do not filter power or inference inputs. The compact report is
not a decision gate; inspect each underlying artefact and record any manual
panel hand-off.
Use the Python API
For file-based inference, initialise the public analyser with a config and data
path:
Direct-data construction is also supported by GeoLiftAnalyzer; the panel must
be wide with units as rows and datetime-like periods as columns, with a unit-
indexed treatment-period series. Use the Python API reference
for signatures.
Power is available through geolift.power.SparseSCPowerCalculator. Donor
screening is available through geolift.donor_evaluator.DonorEvaluator, but
neither is re-exported from the package root. Prefer the CLI for versioned
file-based runs because it writes the maintained artefact family.
Validate a Power Simulation
Treat a power run as a model requiring diagnostics.
Reproducibility
Repeat the same CPU run with the same seed and compare the CSVs. Record the
package version, input hash, YAML, seed, and execution backends.
Monte Carlo precision
Use power_ci_lower and power_ci_upper. If the interval straddles the target
power, increase simulations before making a boundary decision. The interval
quantifies simulation-count uncertainty only; it does not include uncertainty
about the DGP specification.
DGP plausibility
Review dgp_rank, dgp_explained_var, and dgp_factor_dynamics. Compare
observed and simulated distributions outside GeoSC where the decision is
material: unit means and variances, cross-unit correlations, autocorrelation,
seasonal patterns, extremes, and zeros. The current DGP does not model calendar
effects or heteroskedastic idiosyncratic noise explicitly.
Grid stability
Power should usually rise with larger injected effects in a well-resolved
simulation, but finite Monte Carlo estimates can move up or down. Investigate
large reversals, high failure rates, coarse placebo p-values, or sensitivity to
rank, history window, seed, donor eligibility, and effect pattern.
Do not call the run validated merely because all rows are valid. That flag
requires zero failed simulations. Failed rows retain a conditional rejection
rate and completion bounds, but ordinary power and its interval are unavailable.
Do not select a design from those conditional rates or interpret an all-failed
row as zero power. Remove the retired power_failure_rate_threshold key and
regenerate older CSVs; decision consumers require current schema 2.0.